

GUI-decisions
Collection
Decision models for GUI grounding • 5 items • Updated
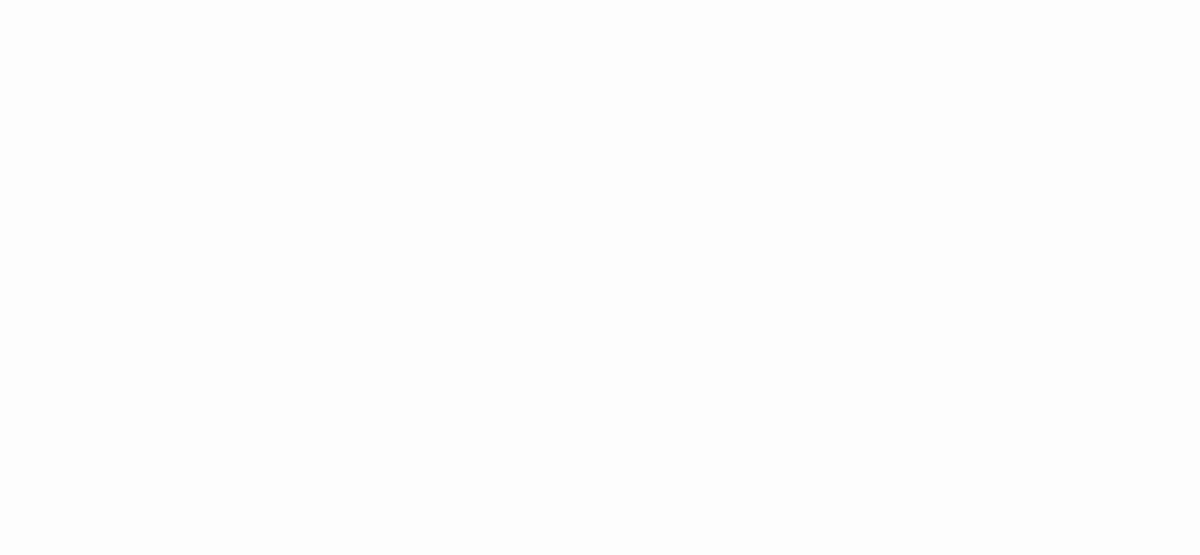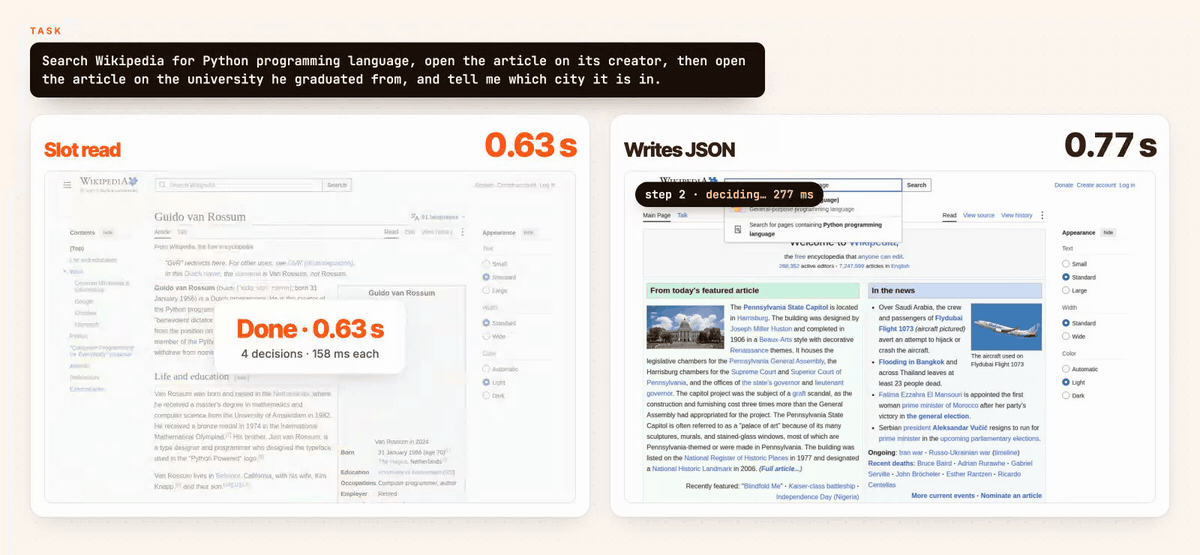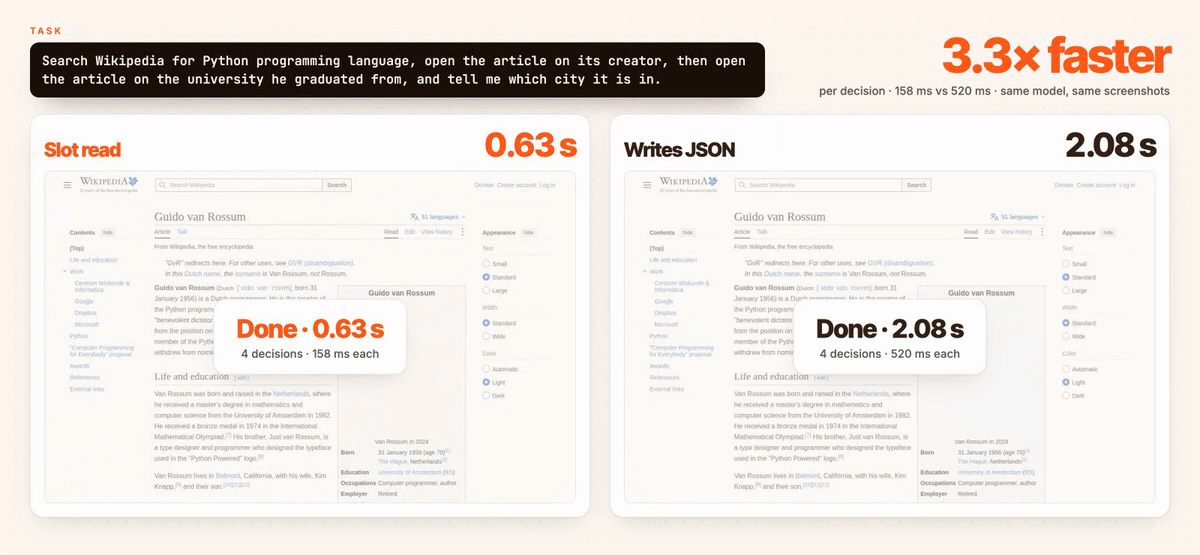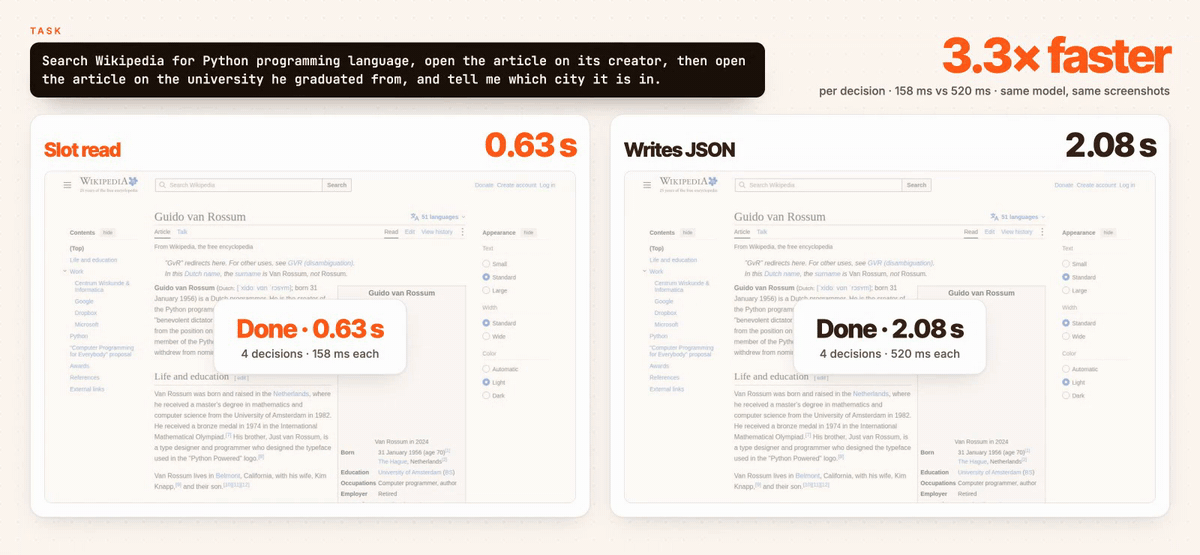
Same model, same screenshots: reading slots (left, 158 ms per decision) against writing the step as JSON (right, 520 ms). Try it in the Space.
google/gemma-4-31B-it with the slot-reading LoRA merged in (bf16), which makes computer-use decisions readable from one forward pass instead of decoded: the action, the point (256 bins per axis), a swipe's end, the key and the scroll, all as next-token distributions at fixed slots. It also reads boxes (centre + log size) and coarse masks (centre + 24 rays) for general objects.
From the blog post Stop Decoding Coordinates: 3× Faster Computer-Use Grounding (run E3). The LoRA alone: GUI-Decisions-31B-LoRA. Try it: GUI-Decisions Space.
The assistant turn is a fixed template; every slot ends in a placeholder ( ___):
action: ___ x: ___ y: ___ x2: ___ y2: ___ key: ___ sdir: ___ samt: ___
A slot's answer is the next-token distribution at the token before its placeholder, restricted to the
slot's labels (slotread_config.json lists them: action words, and 256 single-token "byte" labels per
coordinate). Training used cross-entropy against soft ordinal (Gaussian) targets, so the bins form a
real distribution over the screen.
Served in bf16 on one RTX PRO 6000 a computer-use step takes 190 ms (median over 60 cold screenshots). The LoRA on the NVFP4 base is faster (152 ms) and keeps the base model for text steps; use this merged model when you want one plain checkpoint.
1. Install vLLM 0.30 and the reader (slotread, from the code repository):
git clone https://github.com/infinitylogesh/gui-decisions && cd gui-decisions
pip install "vllm==0.30.*" -e .
bash serving/patch_vllm.sh                 # recommended: 256 label ids per request
2. Serve (bf16, 62 GB of weights: one 80–96 GB GPU):
vllm serve infinitylogesh/GUI-Decisions-31B --served-model-name gui-decisions --port 8001 \
  --max-model-len 8192 --gpu-memory-utilization 0.85 --max-logprobs 300 --enable-prefix-caching \
  --mm-processor-cache-gb 0 --api-server-count 8
3. Read steps and boxes:
from PIL import Image
from slotread.client import SlotModel

m = SlotModel("gui-decisions", "infinitylogesh/GUI-Decisions-31B")   # server: VLLM_URL, default http://127.0.0.1:8001
step = m.decide(Image.open("screenshot.png"), "turn on dark mode")   # {'action': 'click', 'x': 0.928, 'y': 0.247, 'ms': 190.0}
box = m.box(Image.open("photo.jpg"), "the red frisbee")              # {'box': [x1, y1, x2, y2], 'ms': ...}, in [0, 1]
decide reads action, x and y first, then only the slots the action needs (key for press, sdir
and samt for scroll, x2 and y2 for swipe). x and y are fractions of the screenshot's width and
height. For type / answer steps, serve the base model as well and pass its name as text_model= (the
merged weights only answer slots).
What a read is. For each slot, SlotModel sends one chat request whose assistant turn is prefilled up
to that slot, and asks vLLM for the log-probabilities of exactly that slot's labels; nothing is generated
beyond one token. The requests for one step run in parallel and share the image through vLLM's prefix cache:
{"model": "gui-decisions",
 "messages": [{"role": "system", "content": [{"type": "text", "text": "<the task's system prompt, from slotread_config.json>"}]},
              {"role": "user", "content": [{"type": "image_url", "image_url": {"url": "data:image/jpeg;base64,..."}},
                                           {"type": "text", "text": "Please generate the next move according to the UI screenshot, instruction and previous actions.\n\nInstruction: turn on dark mode\n\nPrevious actions:\nNone"}]},
              {"role": "assistant", "content": [{"type": "text", "text": "action: ___ x:"}]}],
 "add_generation_prompt": false, "continue_final_message": true, "chat_template_kwargs": {"enable_thinking": false},
 "max_tokens": 1, "temperature": 0, "logprobs": true, "top_logprobs": 1, "return_tokens_as_token_ids": true,
 "logprob_token_ids": ["<the 256 label ids of slot x, from slotread_config.json>"]}
The slot's answer is the softmax over those labels: the argmax for action; for a coordinate, the argmax
bin refined by its ±2 neighbours (bin k of 256 is the value (k + 0.5) / 256 across the screen).
Notes:
patch_vllm.sh raises vLLM's per-request logprob_token_ids cap from 128 to 256, so a 256-bin slot is
one request. Without it, set MAX_LABEL_IDS=128 for the client (each coordinate then takes two requests).--api-server-count 8: a single API-server process serializes a step's parallel slot requests.
--mm-processor-cache-gb 0: vLLM 0.30's media cache raced on concurrent requests for the same image.IMG_FMT=png IMG_MAX_PX=0), as the evaluations did.previous takes the earlier steps as numbered lines, e.g. "1. click(One way)\n2. click(From)".from PIL import Image
from slotread.local import LocalSlotModel
m = LocalSlotModel.from_pretrained("infinitylogesh/GUI-Decisions-31B")
step = m.decide(Image.open("screenshot.png"), "turn on dark mode")
box = m.box(Image.open("photo.jpg"), "the red frisbee")
This merged model in bf16 with transformers (slotread.local), against the published evaluation of the
LoRA (NVFP4 base, vLLM), case by case on the same sets (paired bootstrap 95% interval on the difference):
| evaluation | this model | published LoRA | difference |
|---|---|---|---|
| ScreenSpot clicks (1,272): point inside the element | 0.869 | 0.866 | +0.003 [−0.006, +0.013] |
| computer-use steps, held-out AGUVIS (1,600) | 0.650 | 0.659 | −0.009 [−0.021, +0.003] |
| RefCOCO val photo boxes (3,811): mean IoU | 0.770 | 0.770 | +0.000 [−0.003, +0.003] |
| COCO val2017 boxes (1,000): mean IoU | 0.744 | 0.742 | +0.002 [−0.002, +0.006] |
No difference is significant. Merging rounds the LoRA's small weight changes into bf16: against the unmerged LoRA on the same bf16 base (0.659 on computer-use steps, exactly the published score) the merged model trends lower on steps (−0.009 [−0.019, +0.001], McNemar p 0.08; 38 of 1,600 actions differ), while clicks and boxes are unchanged. For the closest match to the published numbers, or to write text steps, use the LoRA on the base model. A forward pass reading every slot takes 150–210 ms in plain transformers (bf16, one RTX PRO 6000); served on vLLM with NVFP4 weights a step takes ~146 ms, against 472–546 ms for the base model writing its native JSON.
LoRA r 16, alpha 32, on the language model's attention and MLP projections. Warm-started from the computer-use run (E) and trained further on a mix of AGUVIS computer-use steps (5,000), Wave-UI element clicks (1,000) and boxes (4,000), RefCOCO photo boxes (5,000) and RefCOCO masks (6,000). One RTX PRO 6000, about 4 hours.
@article{umapathi2026slotreading,
  title   = "Stop Decoding Coordinates: 3.5× Faster Computer-Use Grounding",
  author  = "Umapathi, Logesh Kumar",
  journal = "logeshumapathi.com",
  year    = "2026",
  month   = "Oct",
  url     = "https://logeshumapathi.com/blog/2026/10/06/slot-reading.html"
}